What Is Autoscaling? CPU and Memory Thresholds Explained Simply
What is autoscaling? Autoscaling is a cloud computing technique that automatically increases or decreases computing resources according to an application’s workload. Instead of manually adding servers when traffic increases, autoscaling adjusts capacity based on predefined rules, helping applications maintain performance while controlling infrastructure costs.
Understanding CPU and memory thresholds makes autoscaling easier to manage. CPU usage indicates how much processing power an application consumes, while memory usage shows how much RAM it needs. By setting suitable thresholds, businesses can respond to traffic spikes, reduce unnecessary resource consumption, and keep applications running smoothly.
How Autoscaling Works in Cloud Infrastructure
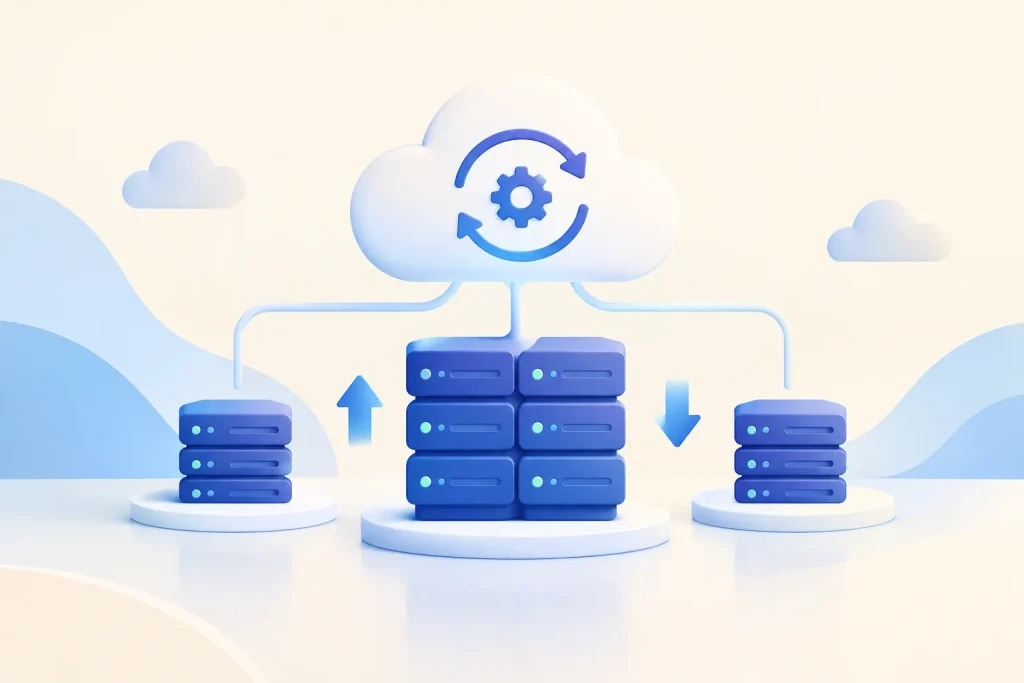
Autoscaling monitors resource usage and workload conditions, then adjusts computing capacity when predefined rules or scaling policies are triggered. Depending on the platform, scaling can add instances, remove instances, or change the resources allocated to existing workloads.
For example, an online store may receive significantly more visitors during a seasonal sale. Autoscaling can add computing capacity to handle additional requests and remove excess capacity when traffic returns to normal.
CPU Thresholds
CPU thresholds trigger scaling when processing usage crosses a configured percentage, indicating that applications may need additional computing capacity.
Memory Thresholds
Memory thresholds monitor RAM consumption, helping detect workloads that need additional memory to operate reliably under pressure.
Scale-Out Actions
Scale-out increases the number of running instances or available resources when demand exceeds the capacity defined by scaling policies.
Scale-In Actions
Scale-in reduces unnecessary capacity when workloads decrease, helping avoid paying for resources that applications no longer require.
What Is Autoscaling and Why Do Thresholds Matter?
To understand what is autoscaling in practical terms, think of thresholds as decision points that tell your infrastructure when to respond to changing workloads. A CPU threshold of 70%, for example, could trigger a scaling action when average CPU utilization stays above that level for a configured period. The exact threshold should reflect your application’s performance requirements. Memory thresholds work differently because high RAM usage does not always mean that an application needs another server. Some applications intentionally retain memory for caching, while others experience memory leaks or sudden increases in consumption. Reviewing memory trends alongside application metrics helps you choose more appropriate scaling rules.
Effective autoscaling combines thresholds with evaluation periods, cooldowns, and workload testing. Scaling immediately after a brief traffic spike may waste resources, while waiting too long can cause slow responses. Monitoring request rates, latency, queue lengths, and CPU or memory usage together provides a more complete picture of when your application needs additional capacity.
How to Choose CPU and Memory Thresholds
Choosing effective autoscaling thresholds requires understanding normal application behavior, identifying performance limits, and testing how your infrastructure responds when demand increases. Start with real monitoring data rather than selecting percentages without evidence.
Set CPU thresholds carefully
Consider beginning load tests around 60–75% average CPU utilization, then adjust the trigger based on response times, workload patterns, and available headroom.
Monitor memory pressure
Establish memory thresholds using observed RAM consumption, container limits, garbage collection behavior, and out-of-memory risks rather than relying on one universal percentage.
Allow time for scaling
Configure evaluation windows, cooldown periods, and minimum capacity to prevent repeated scaling actions caused by short-lived fluctuations in resource usage.
Six Autoscaling Best Practices for Reliable Applications
Measure normal workloads first
Collect CPU, memory, traffic, and response-time metrics during typical usage to establish a reliable baseline before implementing scaling policies.
Choose meaningful thresholds
Set scaling triggers according to observed bottlenecks, service-level objectives, and application behavior instead of copying another application’s configuration.
Define minimum and maximum capacity
Establish instance limits to maintain essential availability while preventing uncontrolled resource growth during unexpected traffic spikes or configuration errors.
Prevent unnecessary scaling
Use suitable evaluation periods, cooldowns, and stabilization mechanisms to avoid adding and removing instances repeatedly during fluctuating workloads.
Test realistic traffic conditions
Simulate normal demand, sudden spikes, sustained high usage, and recovery periods to verify that scaling actions improve performance as expected.
Track costs and performance
Review infrastructure spending alongside latency, errors, and resource utilization to ensure scaling policies balance reliability with operating expenses.
Frequently Asked Questions
A memory threshold is a configured level of RAM utilization that can initiate a scaling action. Its effectiveness depends on memory limits, workload characteristics, and the hosting platform’s scaling capabilities.
Neither metric is universally better. CPU-based scaling suits processing-heavy workloads, while memory-based signals can help identify RAM pressure. Combining multiple metrics often provides more reliable decisions.
Autoscaling can reduce costs by removing excess capacity when demand decreases. However, costs depend on minimum instance counts, scaling limits, resource prices, workload behavior, and the platform’s billing model.